● Released · open model + free API

Point at Khmer.
Get the អក្សរ.

Chakkhu (ចក្ខុ, "eye") reads Khmer and English from photos, scans, old documents, screenshots and chat images, and turns them into text you can copy. Small (18.6M), runs on a normal computer, and tells you which lines it is unsure about.

From the maker of Akkhara: Akkhara types the letters, Chakkhu reads them.
The picture
Chakkhu reads
Preview animation · try the real model in the demo
Why

Khmer is hard for a machine to read

Most OCR tools were built for English, where letters sit in one row, in the same order you type them. Khmer does not work that way.

Letters stack

In ស្ត្រី two letters sit under the first one. One "column" on the page can be three or four letters in the text.

Drawn order ≠ typed order

In កេ the vowel េ is drawn on the left but typed after ក. Reading strictly left to right gives the wrong text.

Khmer + English mixed

Chats, signs and menus mix both: តោះទៅ cafe ថ្ងៃនេះ. Today's free tools are weakest exactly here.

Architecture · the model

A small model built for Khmer

Big AI chat models that "see" pictures make 33–89% mistakes on Khmer. Small, specialised readers win, so Chakkhu is one: 18.6 million parameters (about 19 MB on a phone), trained from scratch, the same size class as the Akkhara keyboard model. Click a figure to zoom.
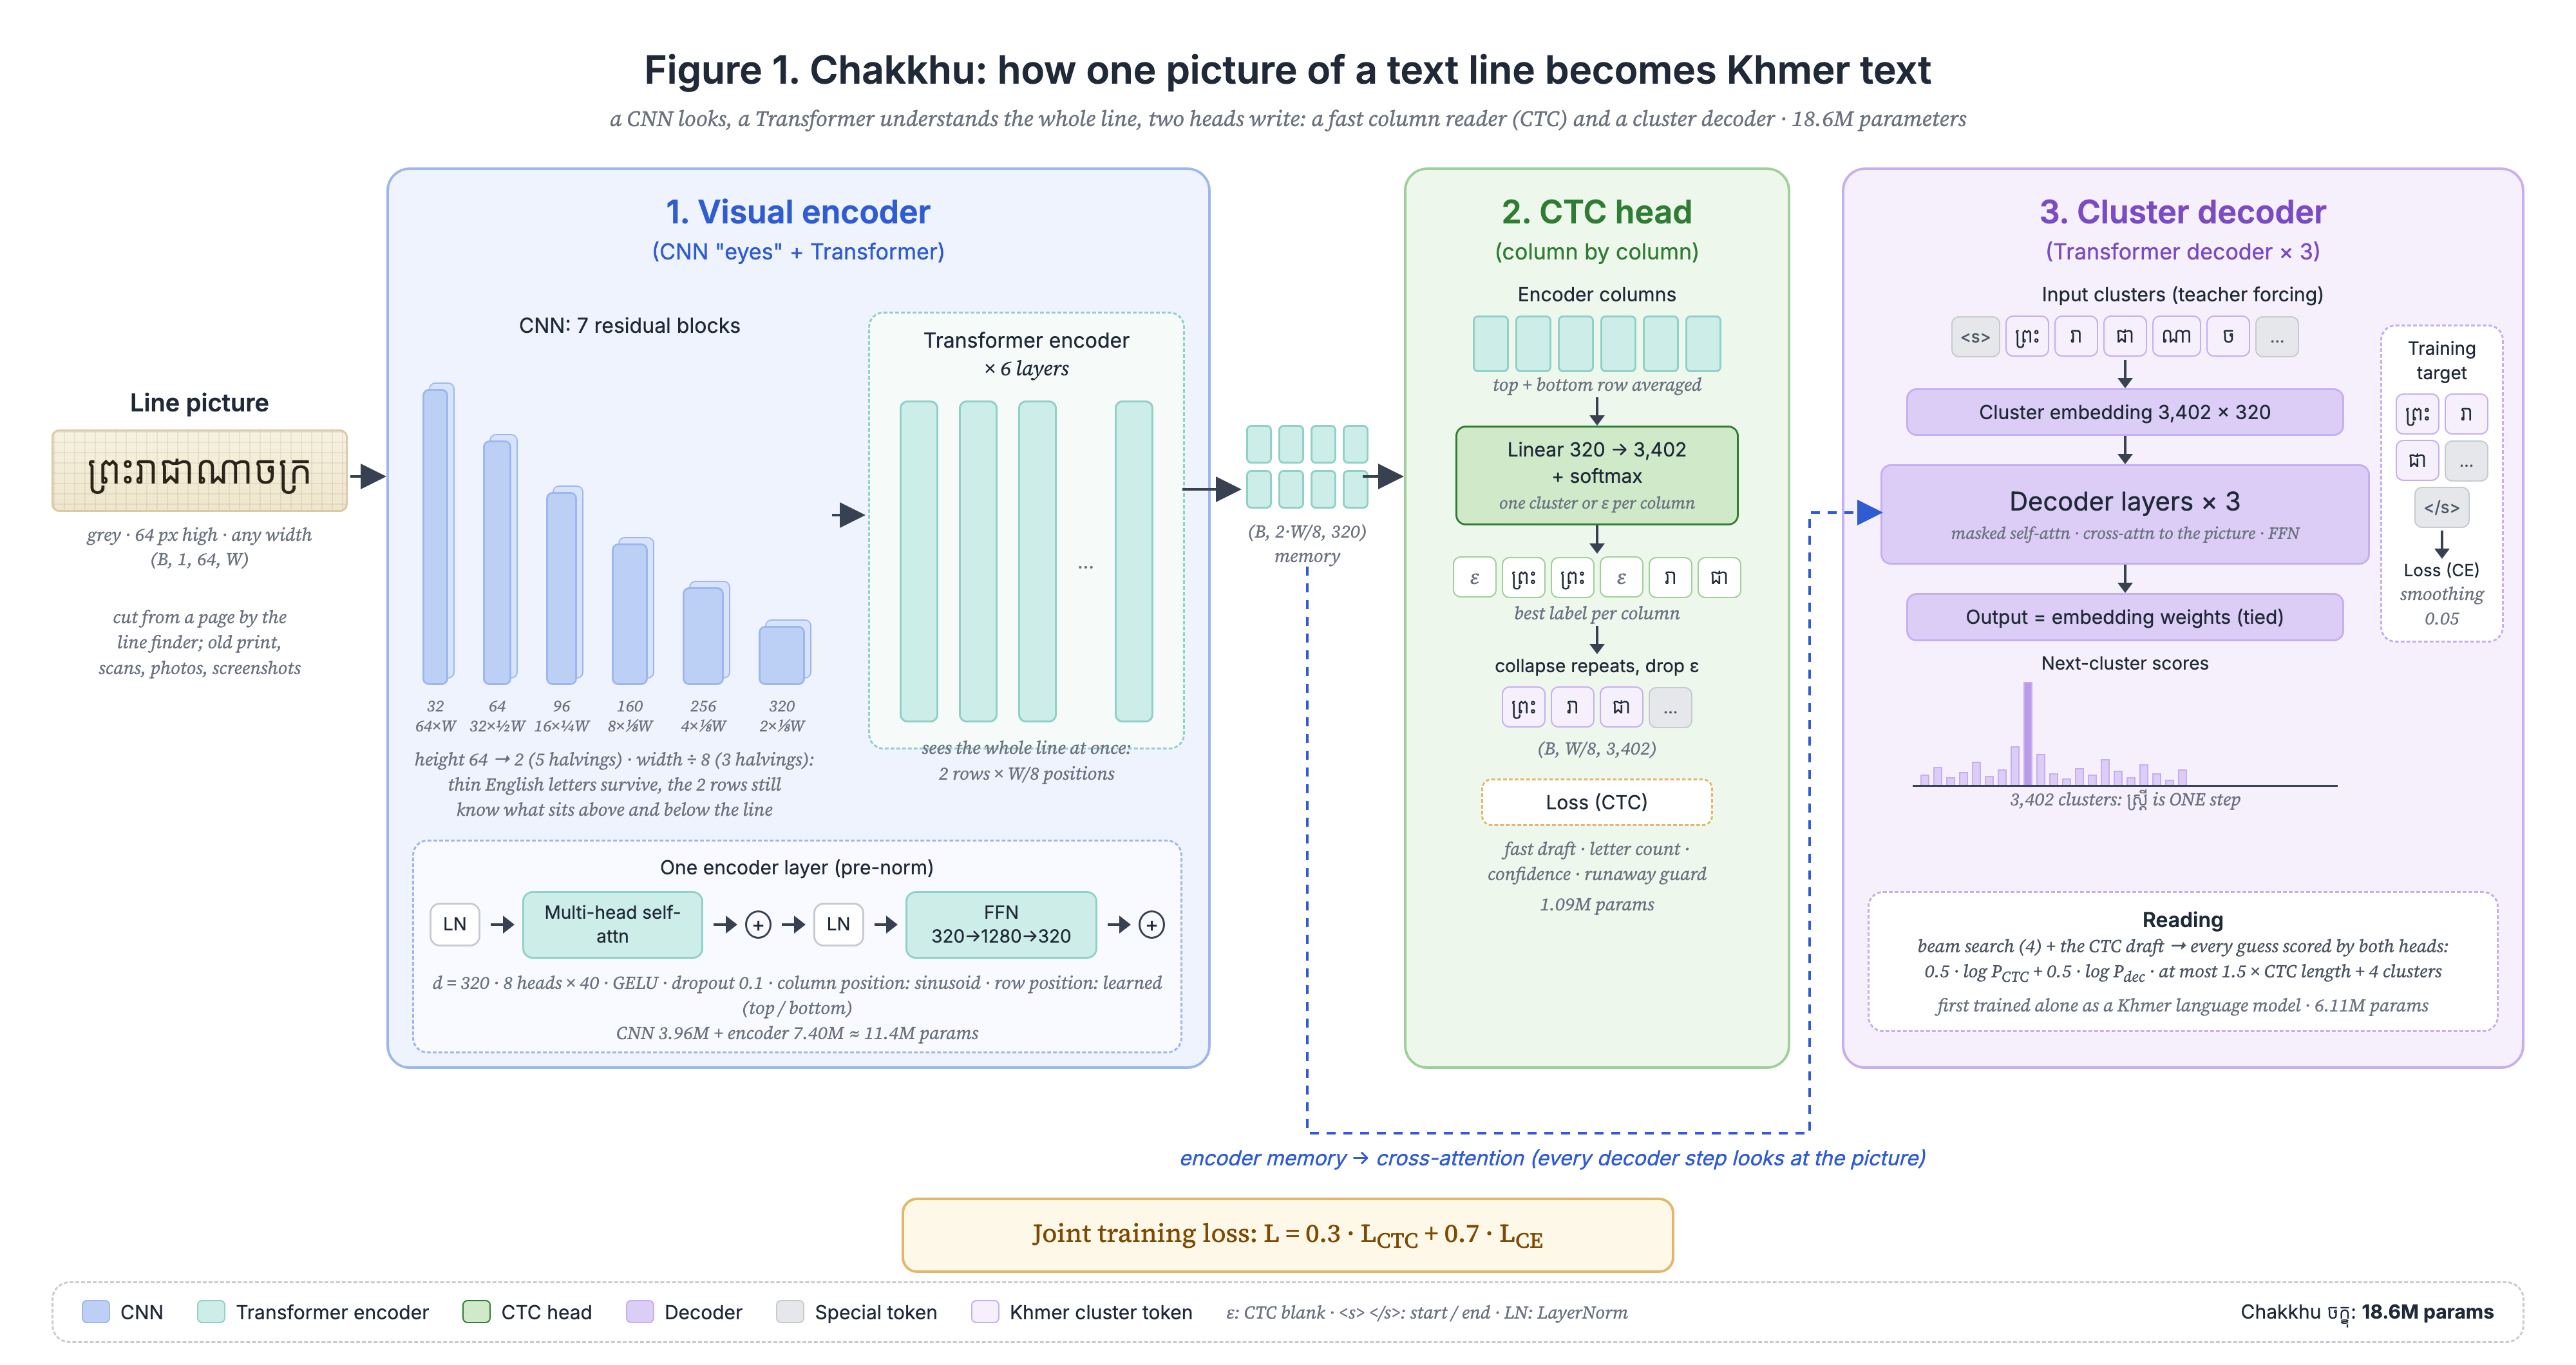
Figure 1. Chakkhu architecture: line picture, CNN with 7 residual blocks, Transformer encoder with 6 layers, CTC head and cluster decoder with 3 layers, joint loss

Why this design

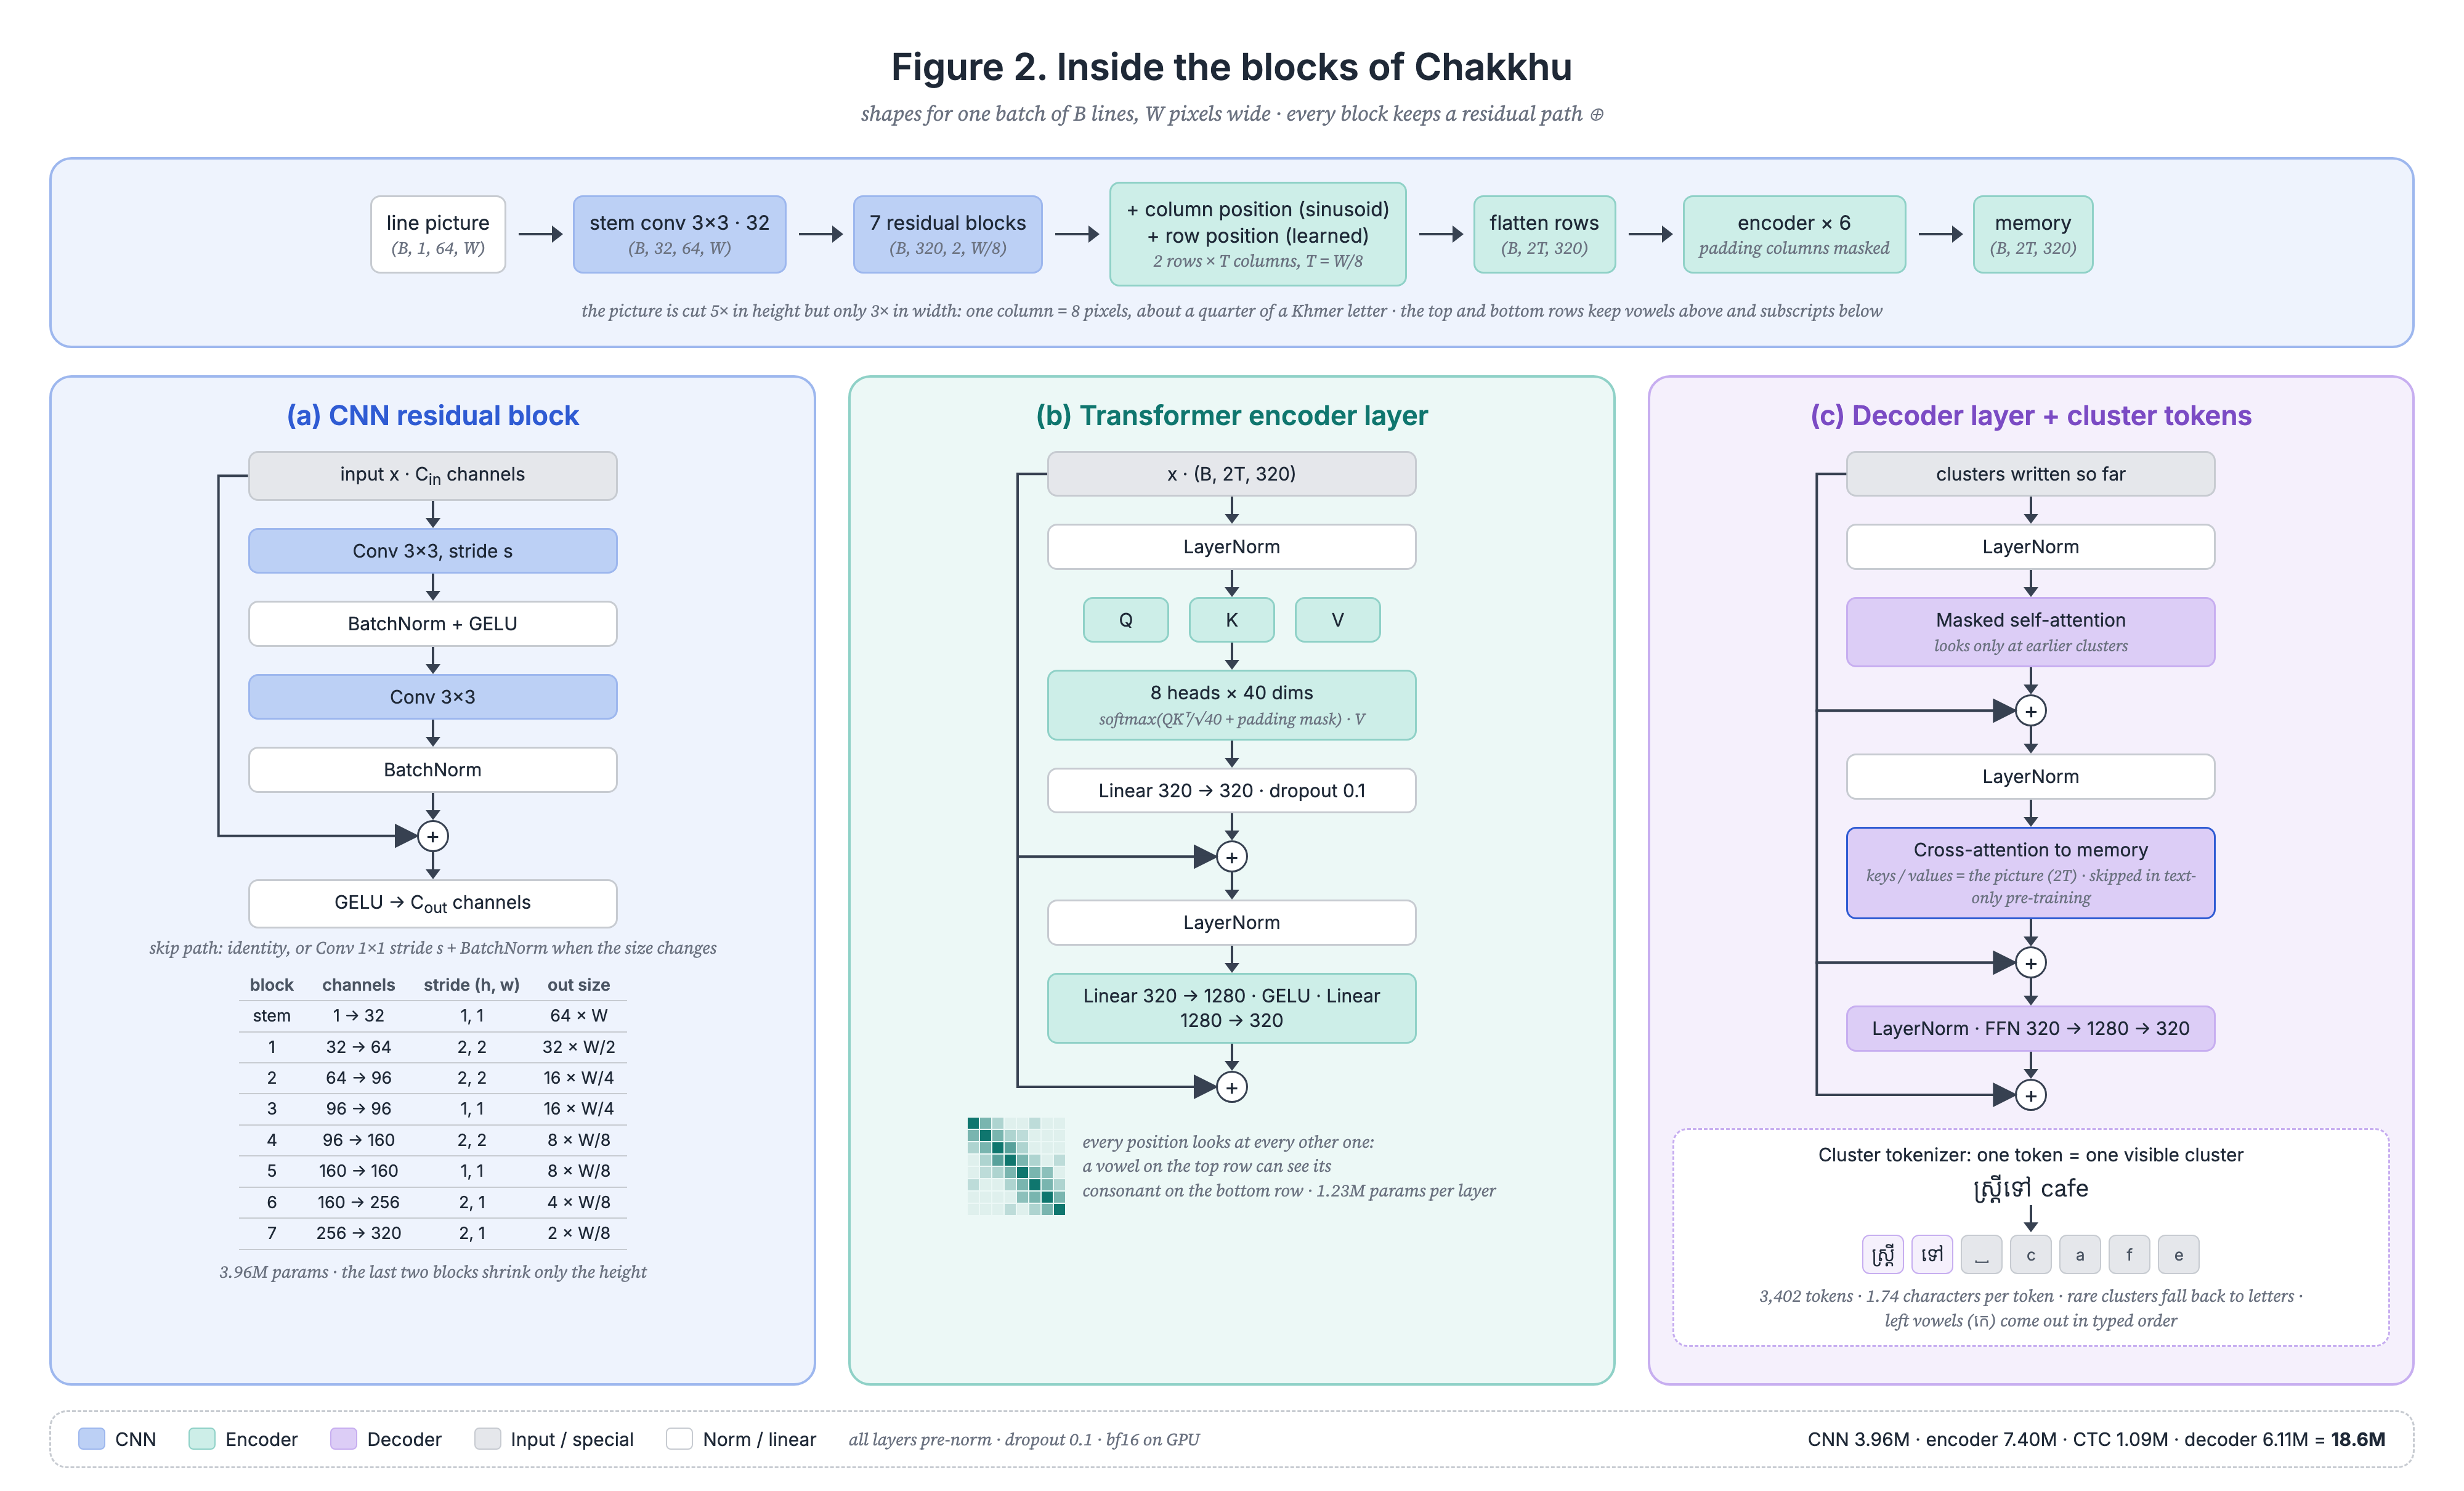
  • Whole clusters, not letters. ស្ត្រី is one token (3,402 in total), so lines are 1.74× shorter and vowels drawn on the left need no reordering.
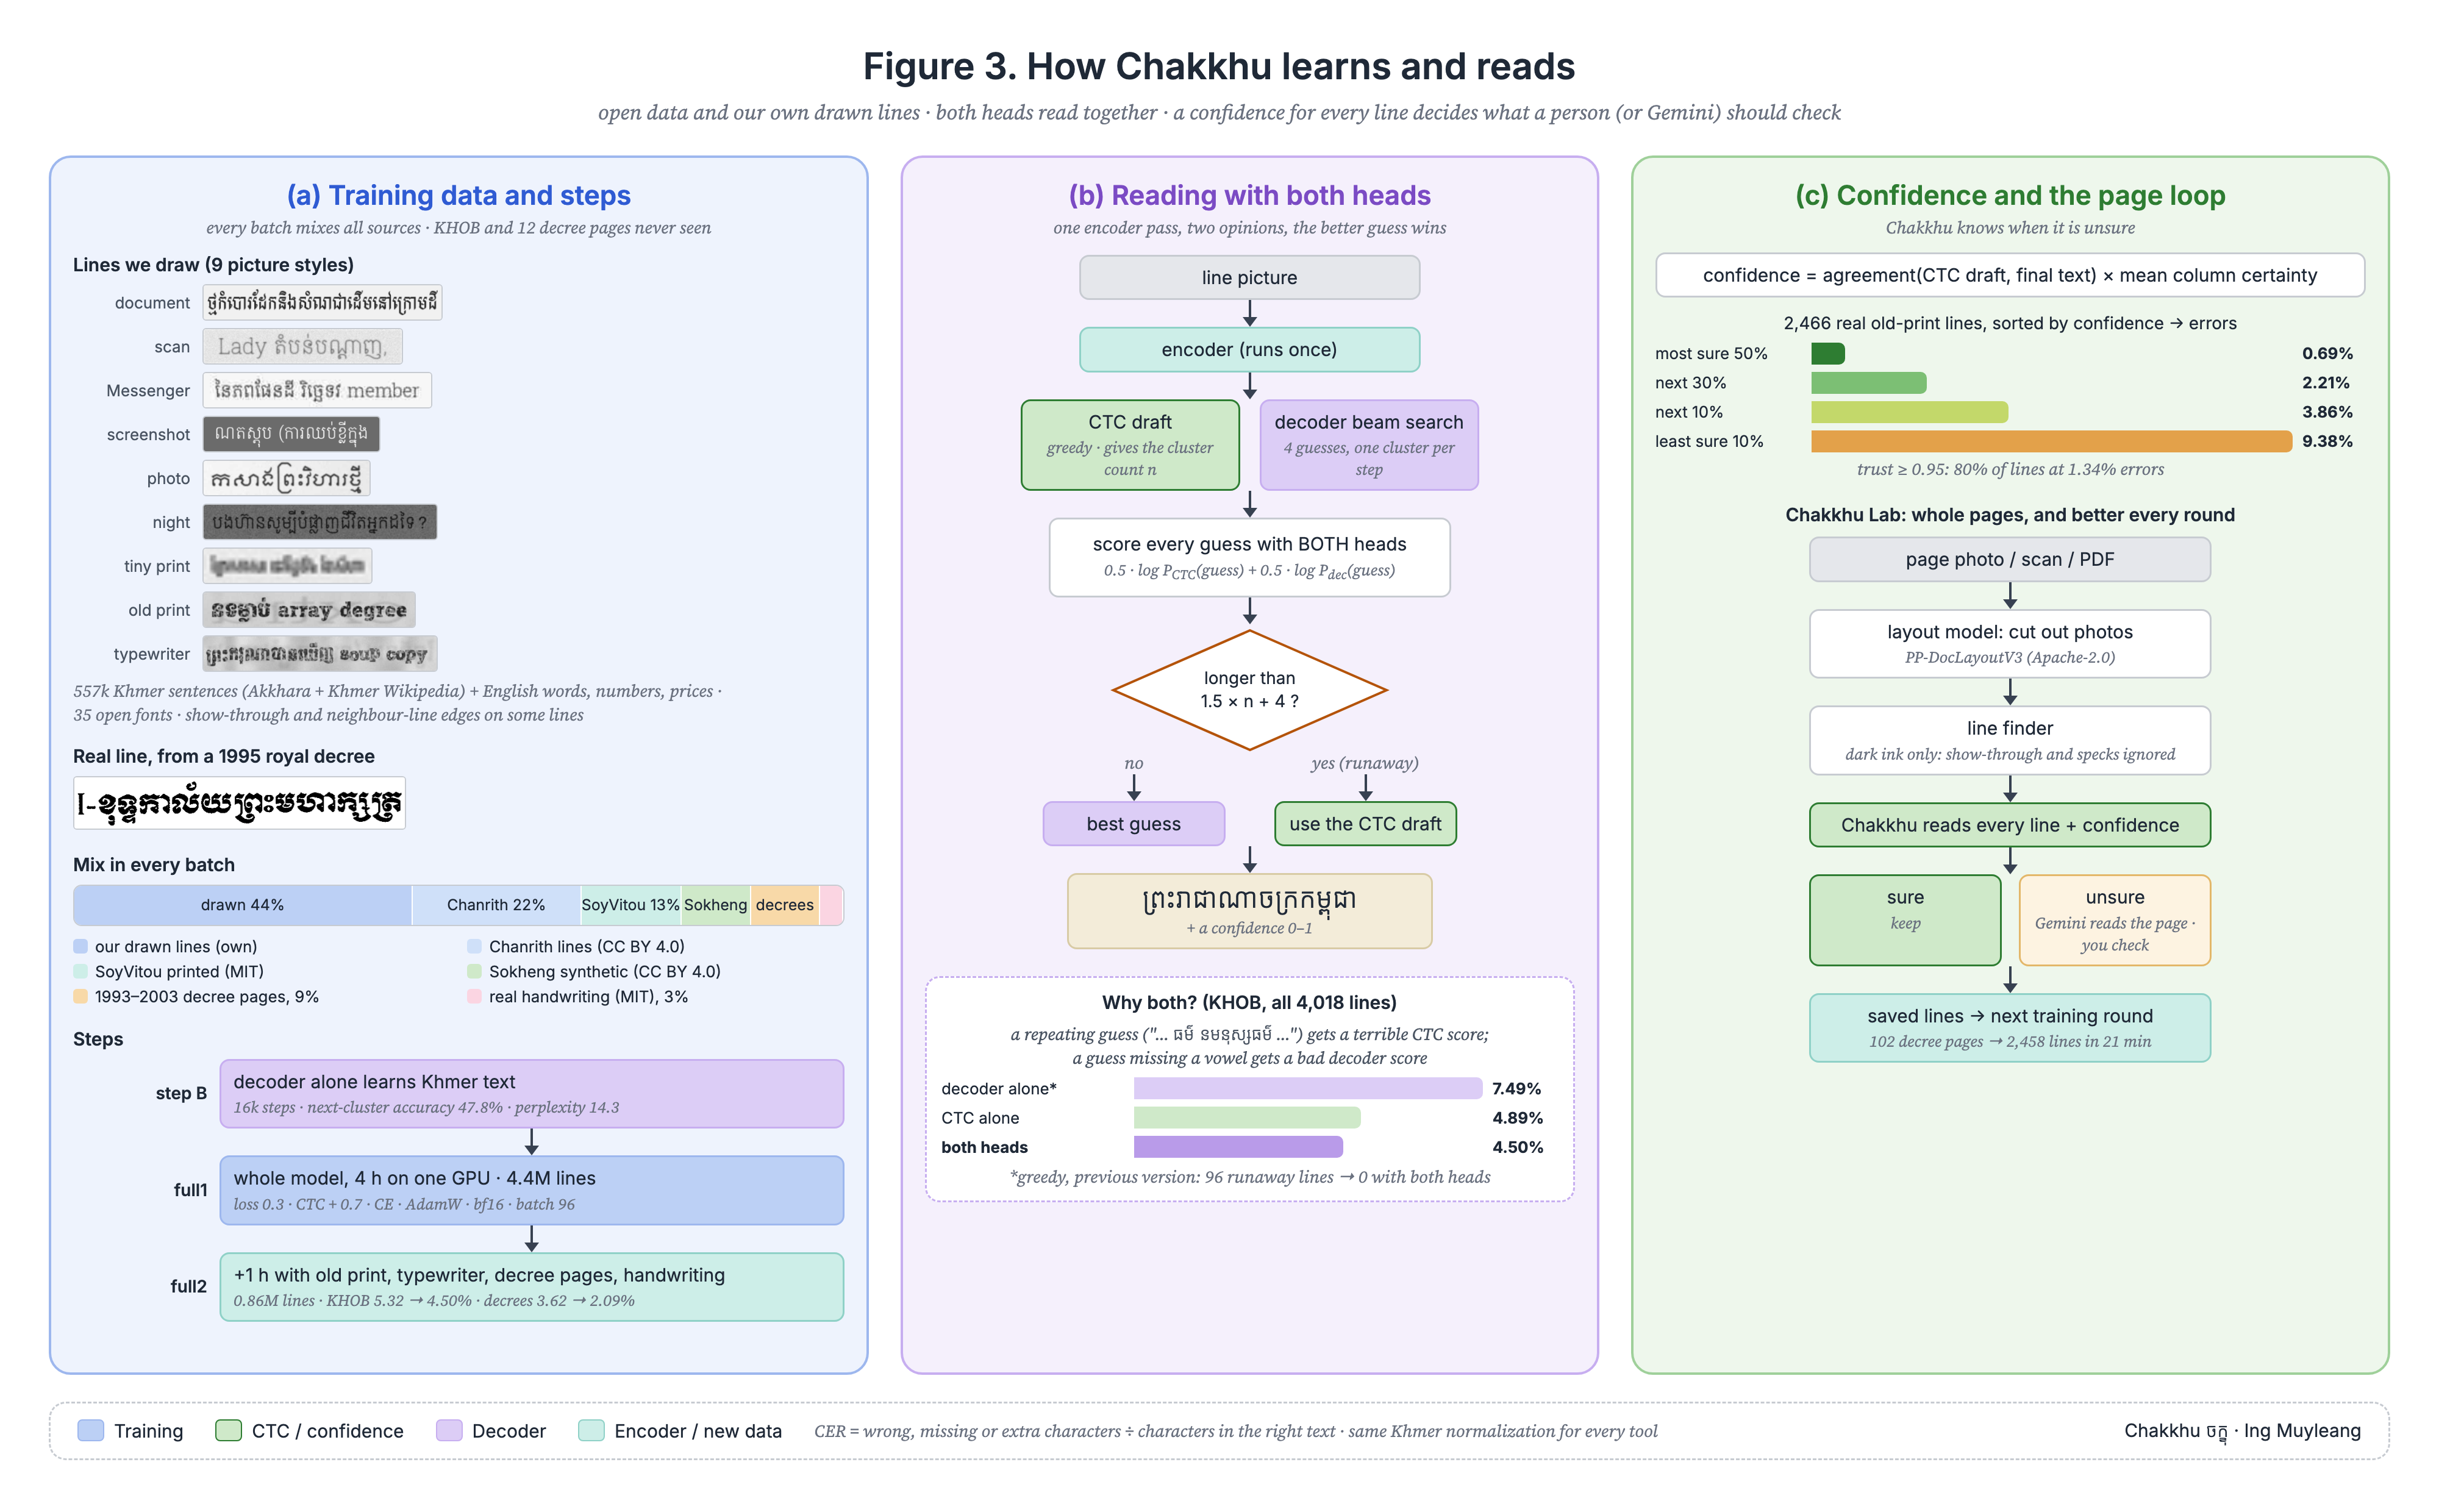
  • Knows Khmer before it reads. The decoder first learns from Khmer text alone, so blurry letters are guessed from the words around them.
  • Keeps the height. 64 px lines, 2 rows inside the model, so stacked letters above and below are not lost.
  • Never invents text. The CTC head counts the letters; if the decoder writes too much, its draft is used. Netra's run-aways were 17% of its errors.
  • Trained on the hard cases: short lines, English, night photos, Messenger images and chat screenshots.

Four ways to build a reader

DesignKhmer?
CRNN + CTCclassic, tiny, fastorder breaks
Big vision AIbillions of parameters33–89% errors
Encoder–decoderTrOCR stylegood, slower
Hybrid CTC + cluster decoderour choice, 18.6Mfast + right order
Figure 2. Inside the blocks: CNN residual block with the 7-block table, Transformer encoder layer, decoder layer and the cluster tokenizer Figure 3. Training data with 9 picture styles and the training steps; reading with both heads and the runaway guard; confidence and the Chakkhu Lab page loop
Report · results

Chakkhu vs the best free tools

All tools tested on KHOB, a public benchmark of real government letters and street photos (4,018 text lines, never used for training). Chakkhu makes the fewest mistakes.

–Chakkhu errors
–Netra-OCR errors
–Tesseract errors
–lines Chakkhu gets fully right

Character error rate by kind of picture (lower is better)

ChakkhuNetra-OCRTesseract 5
Show as a table

Where Chakkhu wins

Documents: about half the mistakes of Netra on clean, Messenger, scanned and phone-scanned pages, and 2.6× fewer on short lines like signs and titles (8.7% vs 22.4%). On old 1990s–2000s government decrees: 2.1% errors. Still behind: street photos (6.4% vs 5.8%, night 11.2% vs 10.6%) and English-only lines.

We fixed the test first

In KHOB, the scanned and Messenger pages reuse the boxes of the clean PDF, so many boxes missed the text. We line up each scan with its clean page before cutting lines, and drop 2 pages whose pictures show a different letter.

How we score

CER = wrong, missing or extra characters ÷ characters in the right answer. Spaces and Khmer letter order are made consistent first (the same rules for every tool). Every labelled line is used (Netra's own 0.96% is on a 325-line selection). Same lines and rules for every tool; Chakkhu never trains on them.

Use it

Open model (Apache-2.0): INGMUYLEANG/chakkhu-ocr. Free demo and API: chakkhu-demo.

from gradio_client import Client, handle_file
c = Client("INGMUYLEANG/chakkhu-demo")
c.predict(handle_file("page.jpg"), "page",
          api_name="/read")
# → text + confidence + box per line

Tools: Netra-OCR recognizer (19M, MIT) · Tesseract 5 with the best Khmer + English models, one-line mode. Benchmark: KHOB (MIT). Tested on 10 Nov 2026.

Data

Only data we are allowed to use

Every training set has a license that allows training (MIT, CC BY or open fonts). Sets that are research-only, non-commercial or without a license are left out.

Training

Our own lines400k Khmer sentences drawn with 35 open fonts in 9 styles: document, scan, photo, night, screenshot, tiny print, old print, typewriter …own
Chanrith Khmer–English linessynthetic, 1M-line sliceCC BY 4.0
SoyVitou printed (62k + per-font)printed Khmer + EnglishMIT
Sokheng synthetic 100kreceipts, menus, price tags, signsCC BY 4.0
Thareah handwritingreal handwritten linesMIT
Cambodian laws & royal decrees89 scanned pages, 1993–2003 (Open Development Cambodia); not protected: copyright law 2003, Art. 10free
Khmer Wikipedia158k sentences, drawn as linesCC BY-SA 4.0
35 Khmer fontsBattambang, Hanuman, Moul, Noto Sans Khmer, Kantumruy Pro …OFL 1.1

Testing (never trained on)

KHOBreal government letters: PDF, Messenger, scanned, phone-scanned; street photos by day and nightMIT
Netra printed wordsMIT
12 decree pagesheld out from the 1990s–2000s set, never trained onfree

Left out

KhmerSynthetic1M (research only) · WildKhmerST (non-commercial, no derivatives) · khmer-sala-ocr-16k (non-commercial) · sets with no license.

Roadmap

Where we are

One step at a time, each with a check before the next.

Done

Collect data & fonts

6 open training sets, 35 fonts, the KHOB benchmark; licenses checked.

Done

Model code + tokenizer

Cluster tokenizer (3,402 tokens) and the 18.6M model, tested: 13 ms per line on a laptop CPU.

Done

Baseline report

Netra-OCR and Tesseract scored on 4,018 real lines (above).

Done

Draw our own lines

Our sentences × 35 fonts × 9 picture styles, incl. old print and typewriter.

Done

Train Chakkhu

4 hours from scratch, then 1 hour more with real 1990s decree pages and handwriting.

Done

Test & release

Beats the baseline: 4.50% vs 5.87%. Open model, demo and free API on Hugging Face.

Next

Self-check & street photos

Use the confidence to check only unsure lines; more street-sign and English training.

Later

In the apps

Find text lines in whole pages, then read them in the Akkhara apps on phone and computer.

Sister projects

More open Khmer AI