● Early test model · try it live

Speak Khmer.
Get the អក្សរ.

Sota (សោតៈ, "ear") turns Khmer and English speech into text you can copy: voice notes, meetings, lectures and phone calls. Small enough to run on your phone, without internet, so your voice never leaves the device.

From the maker of Akkhara and Chakkhu: Akkhara types, Chakkhu reads, Sota listens.
The voice listening
Sota writes
Preview animation. Try the real model below
Try it

Talk to Sota in your browser

Record yourself or upload an audio file. The model (≈33 MB, downloaded once) runs on your own device, so your voice is never uploaded. Early test model: best on clear Khmer speech.

The model loads the first time you use it.
Why

Khmer is hard for a machine to hear

Most speech tools were trained mostly on English. Khmer brings problems they rarely see.

No spaces between words

Khmer is written without spaces, so "word error rate" does not fit. Sota is scored by character error rate (CER), with spaces ignored.

Khmer + English mixed

People say តោះទៅ cafe ថ្ងៃនេះ. Today's Khmer models often write the English words as Khmer sounds instead.

Real life is noisy

Phone calls, street noise, fast talk and many accents. Models tuned on clean read speech lose accuracy exactly here.

Architecture · the plan

A small ear built for Khmer

Sota is trained from scratch: about 26 million parameters (≈33 MB as an int8 file), roughly 23× smaller than Qwen3-ASR-0.6B. It shares Chakkhu's recipe: Khmer clusters as tokens, a fast CTC head plus a cluster decoder, a runaway guard and beam search.
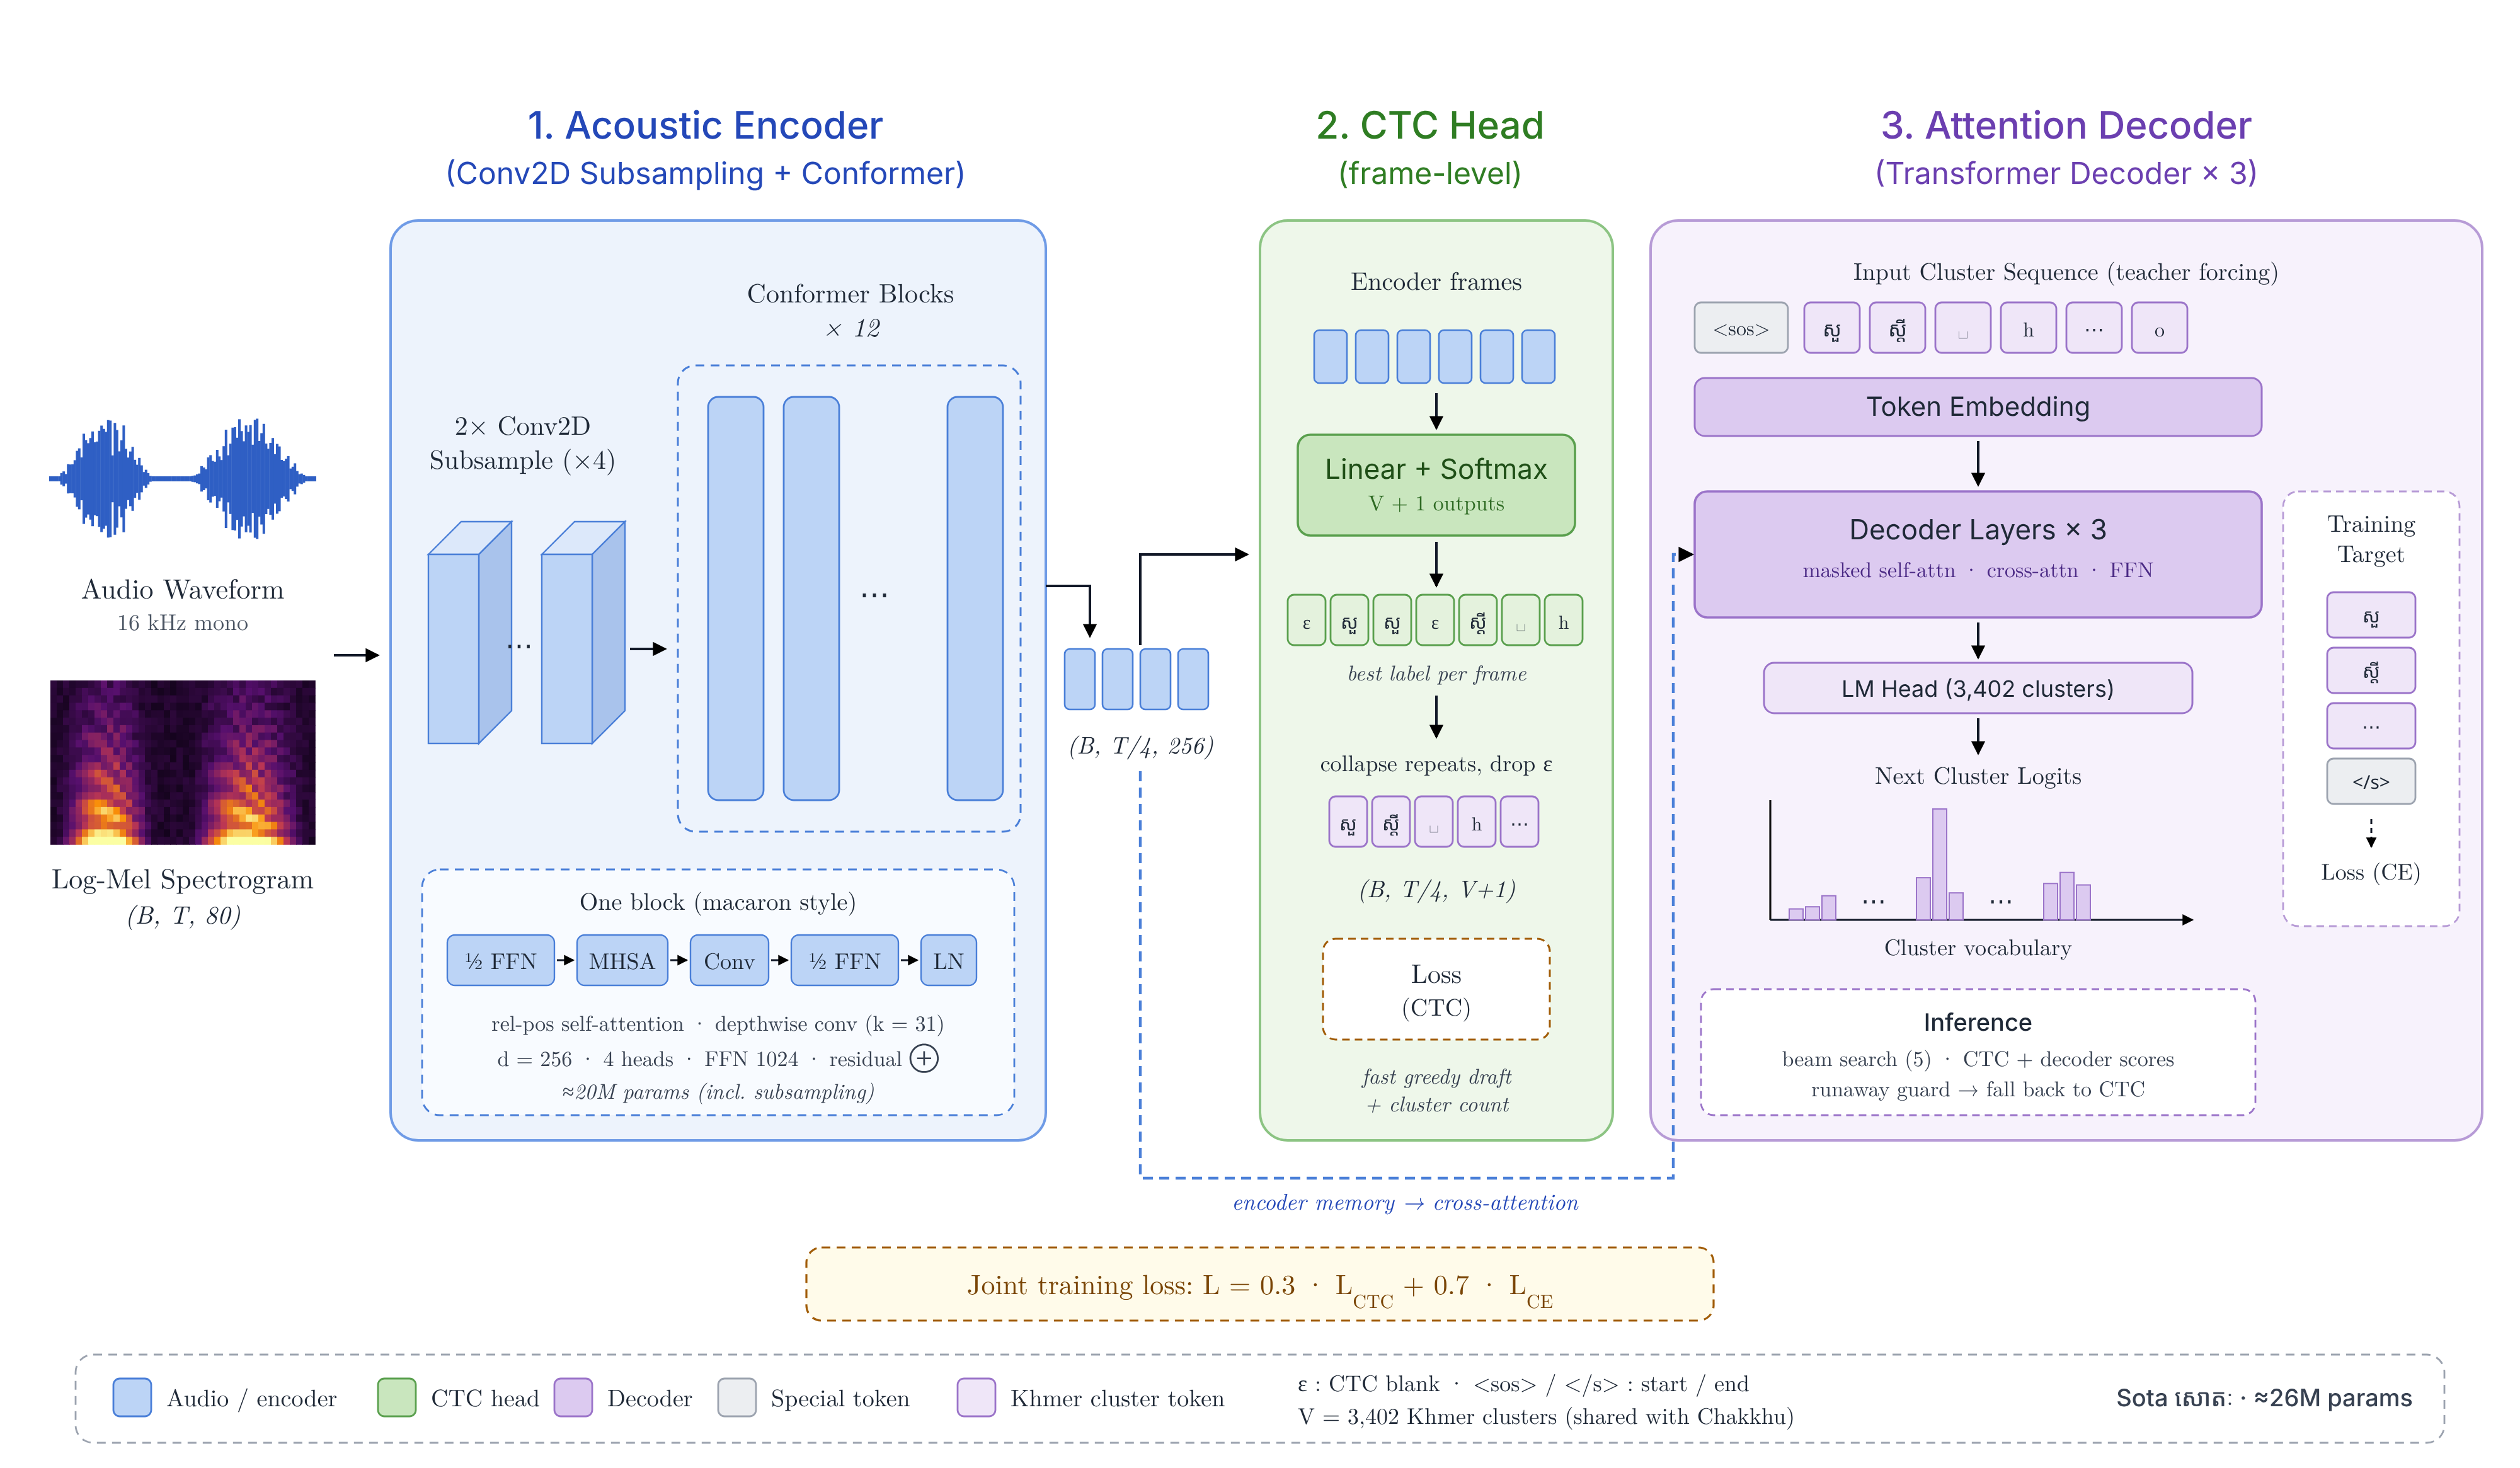
Figure 1. Sota overview: log-Mel spectrogram, Conformer encoder, CTC head and attention decoder with joint loss

Figure 1. Overview. Log-Mel features → Conv2D subsampling → 12 Conformer blocks → CTC head and attention decoder, trained together.
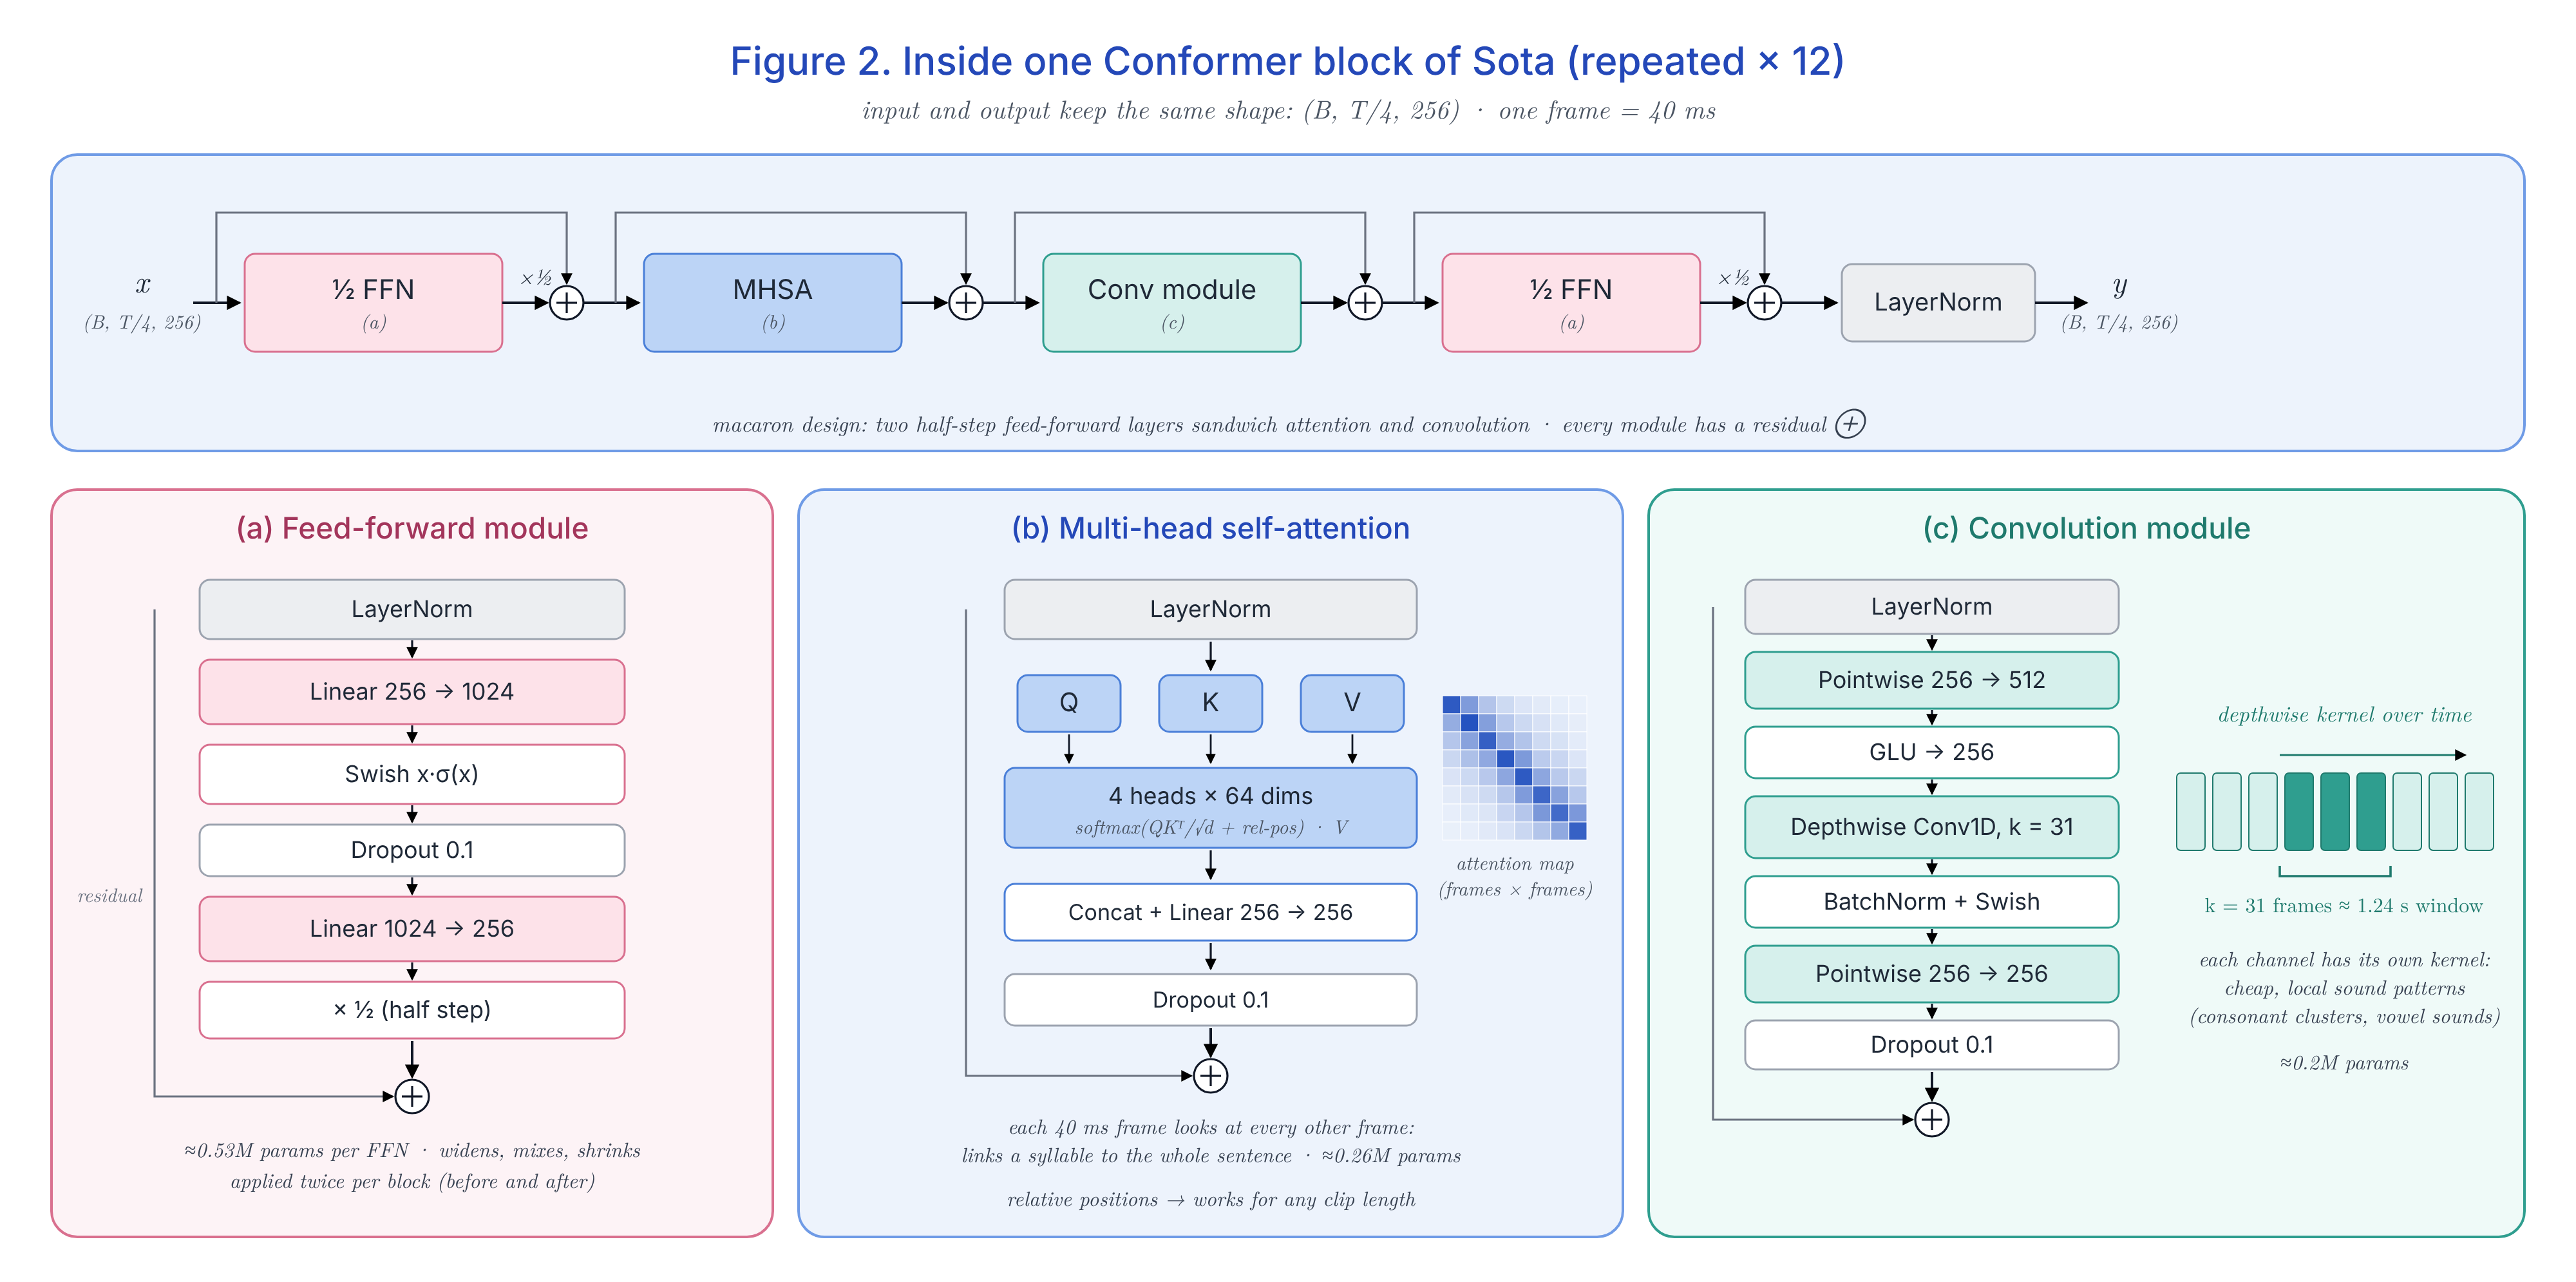
Figure 2. Inside one Conformer block: feed-forward, self-attention and convolution modules

Figure 2. Inside one Conformer block. Attention hears the whole sentence; convolution hears each sound.
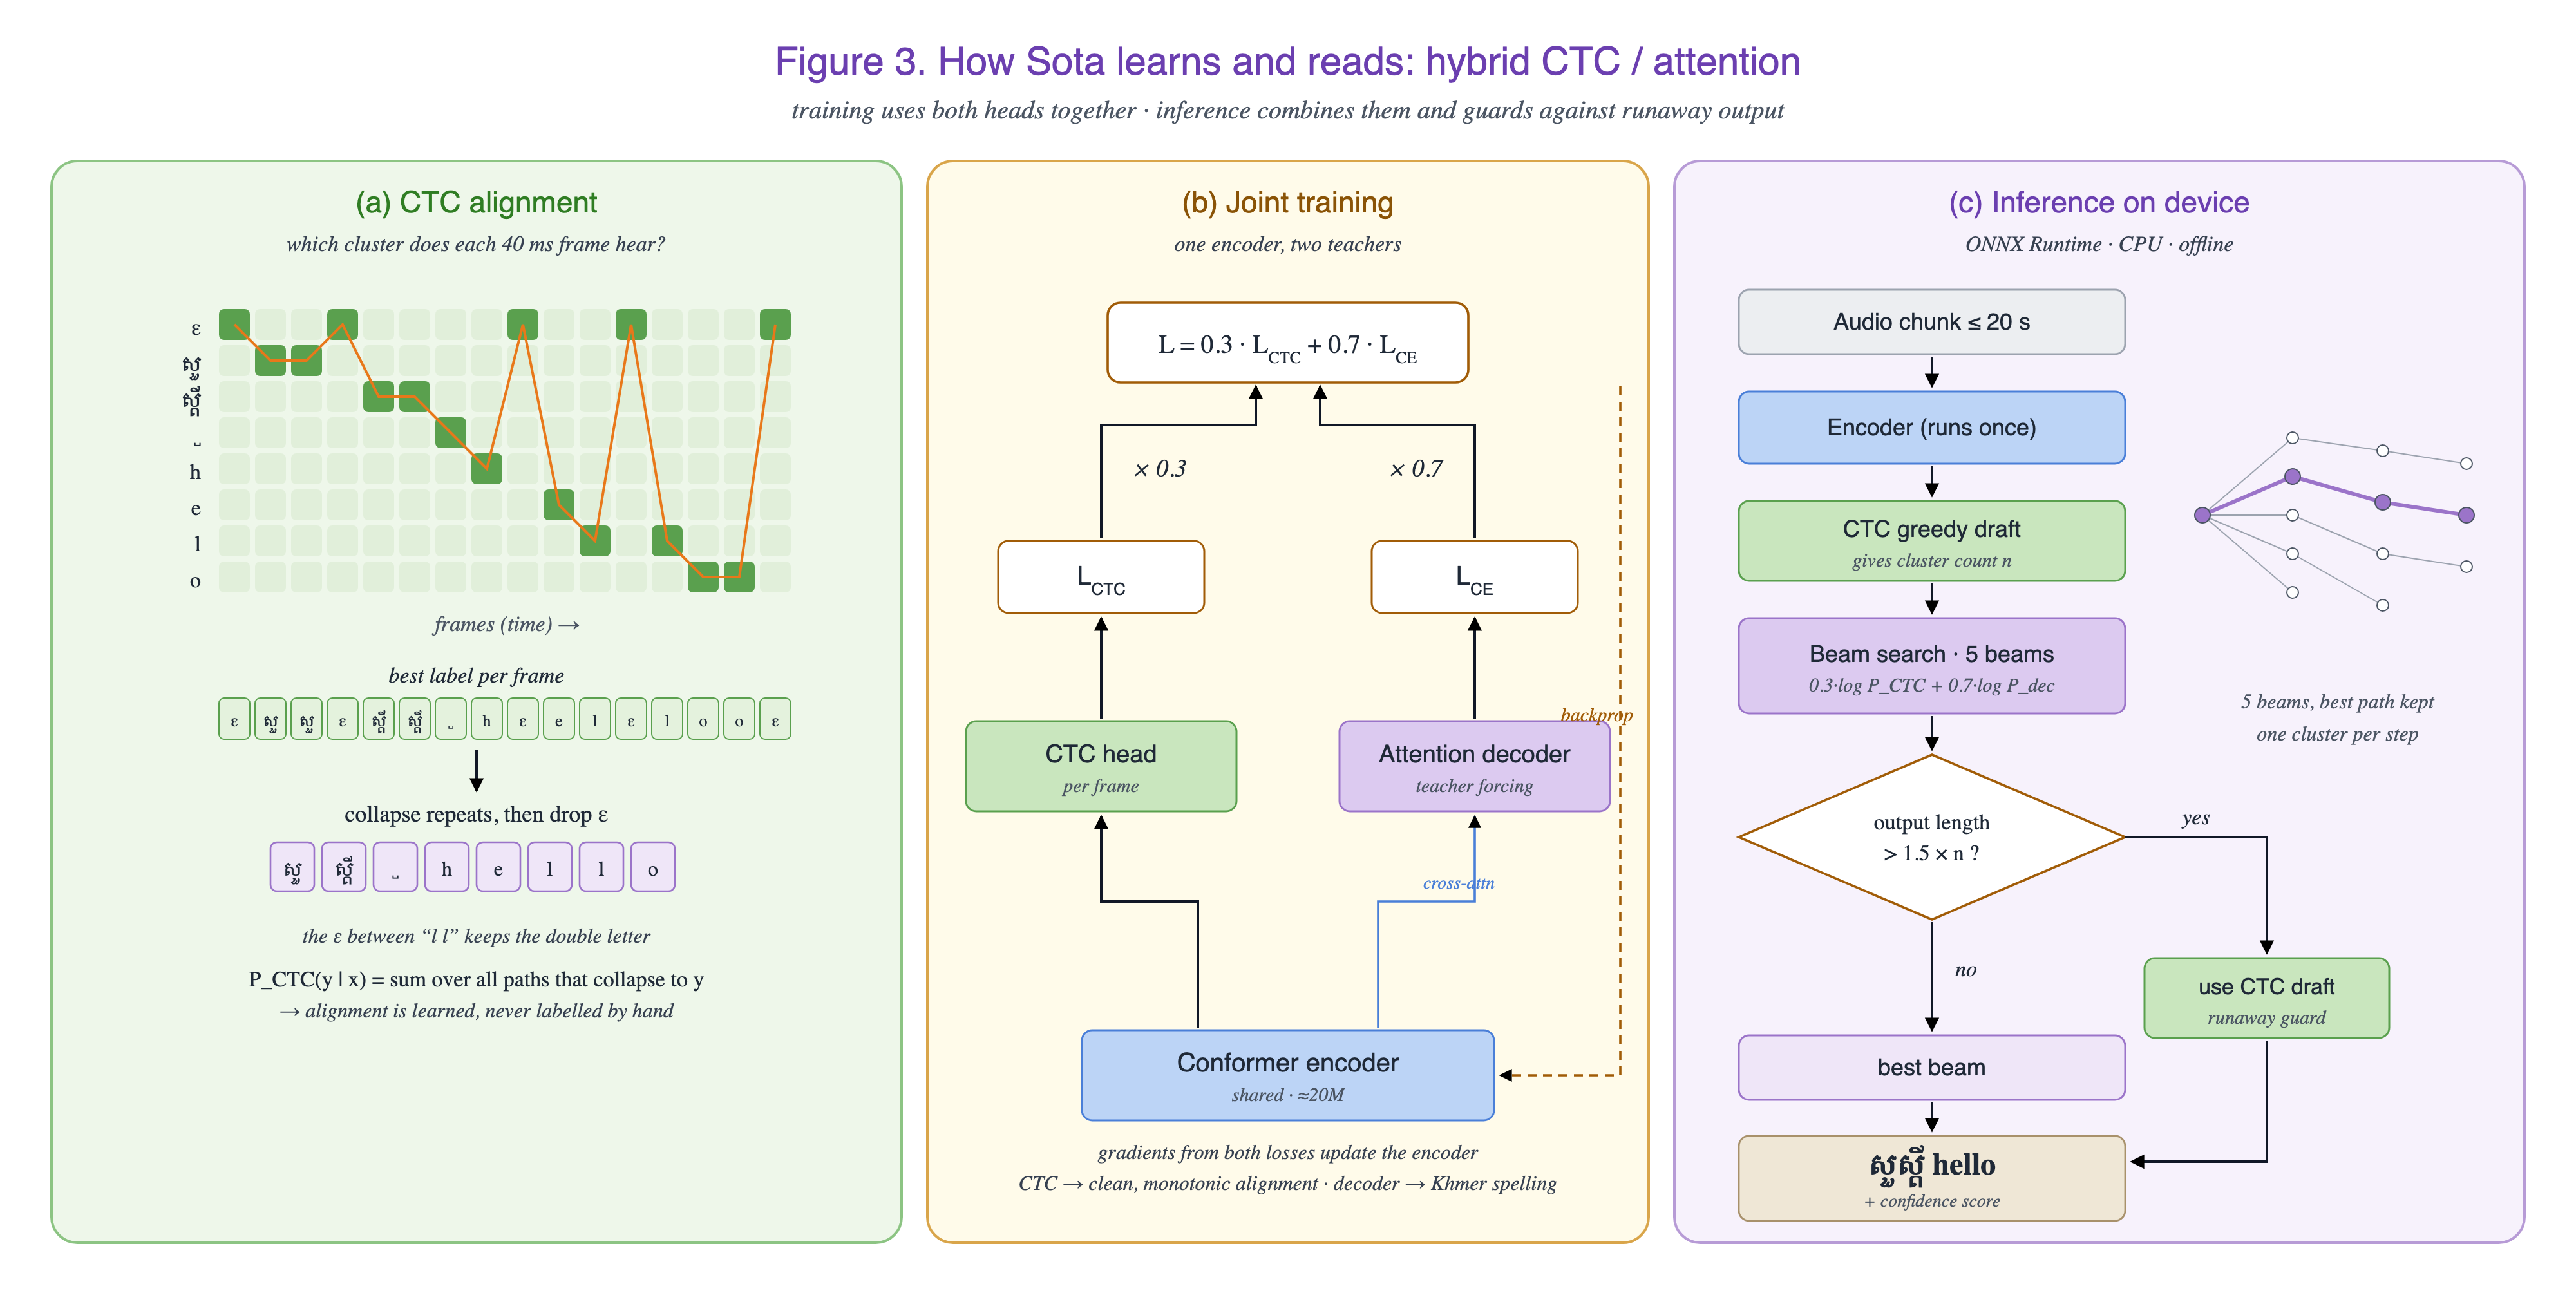
Figure 3. CTC alignment, joint training loss and on-device inference with runaway guard

Figure 3. How it learns and reads. CTC alignment, joint loss, and decoding on the device.

Why this design

  • Whole clusters, not letters. The same 3,402 Khmer cluster tokens as Chakkhu, so ស្តី is one token and both models share one engine.
  • Hears near and far. Each Conformer block mixes convolution (each sound) with attention (the whole sentence).
  • Knows Khmer before it listens. The decoder first learns from Khmer text, so unclear sounds are guessed from the words around them.
  • Never invents text. The CTC head counts the clusters; if the decoder writes too much, the CTC draft is used instead.
  • Trained on the hard cases: noise, speed changes, phone audio and Khmer–English mixing.

Four ways to build a listener

DesignOn a phone?
Fine-tune Whispermultilingual, encoder–decoderslow, may repeat
Fine-tune Qwen3-ASR0.6B parameters, strong on clean speechtoo big
Conformer + CTC onlysmall and fastweak spelling
Hybrid CTC + cluster decoderour choice, ≈26Mfast + right spelling
Benchmark · first results

First results

We tested Sota and the best free Khmer speech models on the same 12 hours of held-out recordings (6,513 clips, 16 speakers never used in training), with the same rules. Lower CER is better.

3.4%Sota (26M) CER
13.2%Qwen3-ASR-0.6B-Khmer CER
18.6%Whisper-small-khmer CER
23×Sota is smaller than Qwen3-ASR

Character error rate by model (lower is better)

ModelSizeAllnxkmerOpenSLR42
Sotafrom scratch · beam 526M · 33 MB int83.40%3.25%5.20%
Qwen3-ASR-0.6B-Khmerfine-tuned Qwen3-ASR0.6B13.20%13.34%11.41%
whisper-small-khmer-v2fine-tuned Whisper small≈244M18.57%19.72%4.61% †

† Whisper-small-khmer was trained on OpenSLR42, so it may have heard these sentences before. Sota with fast CTC decoding (no beam): 3.62% all. Clips with English words: only 4 in this test set, too few to score.

Fair-play notes: these are clean recordings from the same sources Sota trained on (different speakers), so they favour Sota. Whisper-small-khmer was trained on OpenSLR42, which is part of this test set. Phone calls, noise and Khmer–English mixing are not tested yet.

What we compare

Qwen3-ASR-0.6B-Khmer and whisper-small-khmer-v2, the strongest open Khmer models, run on CPU like Sota.

On which audio

Now: 16 speakers held out from training (clean read and spoken Khmer). Next: harder real-life clips (phone calls, noise and Khmer–English mixing), scored separately.

How we score

CER = wrong, missing or extra characters ÷ characters in the right answer. Spaces and punctuation are removed first. Same clips and rules for every model.

Data

What Sota learns from

Every set is checked for a license that allows training before it is used.

Training

Real Khmer speech, ≈237 hourspeople recorded reading and talking; 16 kHz mono, text normalized, split by speaker; dev and test come only from herechecking
Synthetic speech, ≈610 hoursmade by VoxPocket TTS: many voices, styles and Khmer–English sentences; at most half of each epochown
AugmentationSpecAugment masks, speed 0.9 / 1.0 / 1.1, background noise, room echo, phone-call audioown
Khmer text for the decoderthe same sentences Chakkhu learns fromown

Testing (never trained on)

Held-out speakersfrom the real speech, never seen in training (not even as cloned voices)own
Real-life clipsphone calls, street noise, Khmer + English (to collect)own
khmer-asr-compare-eval287 Khmer and code-switched clips on Hugging Face (gated)checking
Roadmap

Where we are

One step at a time, each with a check before the next.

Done

Name & design

Sota សោតៈ, the ≈26M hybrid design and three architecture figures.

Done

Cluster tokenizer

3,402 Khmer cluster tokens, shared with Chakkhu.

Done

Prepare the audio

≈850 h (≈237 h real): resampled, text cleaned, split by speaker, cloned voices and repeated sentences removed.

Done

Baseline report

Qwen3-ASR-Khmer 13.2% and Whisper-small-khmer 18.6% CER on the same 12 h test set.

Done

Train Sota

Decoder learned Khmer text first, then a small test run, then the full run: 100k steps on one GPU. Test CER 3.4%.

Now

Test & release

Early test: web demo, Space and model are live. Next: phone, noise and Khmer–English tests.

Later

In the apps

Voice typing in the Akkhara keyboard, on phone and computer, offline.